Weave
Weave is engineering intelligence software that scores every merged pull request in expert hours, tracks quality, review health and DORA delivery metrics, and attributes output to AI or human authorship. Wooly, its research agent, answers questions about the org with cited sources, while Token Intelligence ties AI spend to shipped work and benchmarks cost per merged PR.
What is Weave?
Weave is an engineering intelligence platform from Workweave Inc. that combines large language models with domain-specific machine learning to measure engineering work. It answers three questions in one system: how much work a change represents, how good that work is, and how much of it AI produced. The company was formerly called Workweave, and the product now lives at weaveos.com while the application runs at app.workweave.ai.
The core unit is the expert hour. Weave's code model, Silk 1, reads the full diff of every merged pull request, estimates how long an expert engineer would need to complete it, and explains the score in plain language. Weave reports 3.3x lower prediction error than its earlier model, with 88 percent of PRs landing within an hour of an expert estimate. One model runs across every engineer, repository and language, so team and organisation comparisons stay on the same scale, and engineers can flag a wrong-looking score to feed calibration back.
Around that score, Weave assembles quality and delivery evidence: incidents traced back to the commits and pull request that introduced them, revert rates by repository and engineer, code churn, review depth, rounds before merge, and reviewer load. DORA measures cover deployment frequency, mean time to recovery, deploy success rate and merge-to-production lead time, benchmarked against percentile tiers drawn from the platform's own customer data rather than a published survey.
AI impact is the differentiator. Weave attributes merged code to AI or human authorship through a hierarchy of methods: verified native API integrations with tools such as Cursor and GitHub Copilot, inferred git co-authorship metadata, and time-series estimates that are always labelled as estimates. It reports AI-assisted share of output by team and work type, separates foreground assistants from background agents, and folds subscription and token spend into AI ROI, where cost per output hour equals attributed AI spend divided by estimated expert hours. Token Intelligence adds spend tracking, budget planning and Dev FinOps reporting across more than 50 AI tools.
Wooly is the research agent layered on top. It takes a question in natural language, resolves the teams and repositories involved, retrieves pull requests, reviews, deploys, agent runs and spend, separates human from AI contributions, and cites the record behind every number; the same agent is reachable through an MCP server. A separate product line, the open-source Weave Router, classifies each coding-agent prompt and sends it to the model with the best quality per token, installed with a single npx command for Claude Code and Codex.
Deployment is cloud by default, with on-premise and air-gapped options for enterprises, SAML or OIDC single sign-on, SCIM provisioning, role-based access and audit logs. Weave holds SOC 2 Type II and reports GDPR and HIPAA compliance, and quotes go-live in under two weeks. Pricing is free on Starter, 50 dollars per engineer per month on Pro and custom for Enterprise, with Router billed separately.
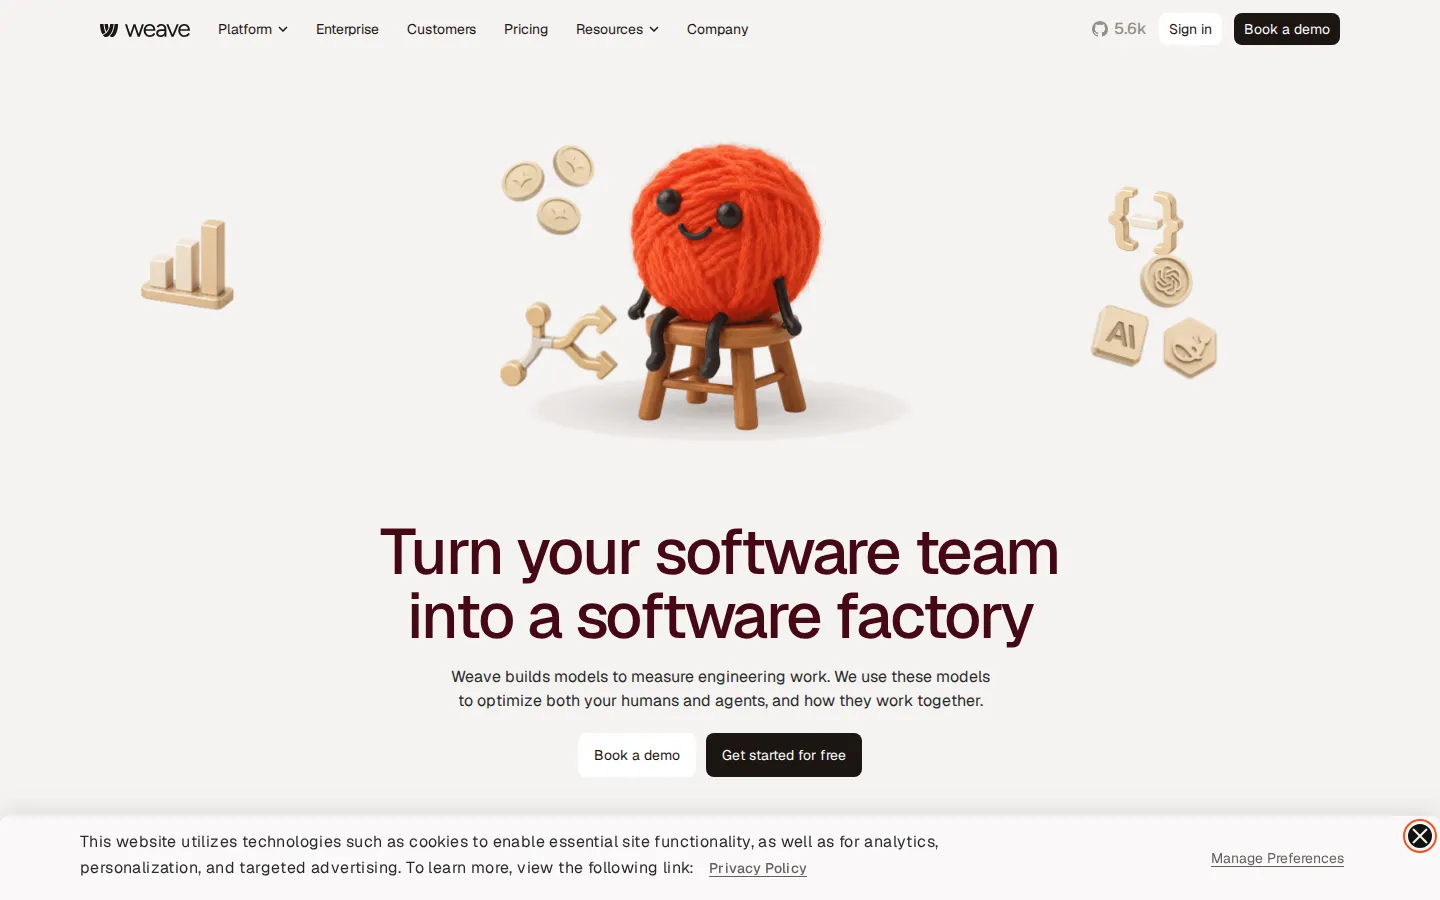
Weave Core Features
Expert-hour output scoring
Silk 1 reads each merged diff and estimates the work an expert would need, with plain-language reasoning and per-PR drill-down.
AI authorship attribution
Verified API data, git co-authorship and clearly labelled estimates split merged code between human and AI contributors.
AI ROI and token intelligence
Connects subscription and token spend to output hours, benchmarks cost per merged PR and supports AI budget planning.
Quality tracing
Links production incidents to the commits and pull requests behind them, alongside revert rates and churn by repository.
Review health
Scores review depth, counts rounds before merge and shows reviewer load, so bottlenecks surface before they slow delivery.
DORA benchmarks
Deployment frequency, MTTR, deploy success rate and lead time compared against percentile tiers drawn from real customer data.
Wooly research agent
Answers natural-language questions about the org, cites every source record and is available in the app or through MCP.
Weave Router
Open-source prompt router that sends each coding-agent request to the cheapest model that still clears the quality bar.
Who is Weave for?
Weave is built for people who are accountable for engineering output and cannot answer basic questions about it with confidence. The primary buyer is a VP of Engineering or CTO at a company with 50 to 2,000 engineers, where AI tools have spread bottom-up and leadership now needs to justify the spend without trusting seat counts or vendor dashboards. They want one number for output and one for the return on AI, and they need both to survive a board review. Engineering managers are the daily users. They use per-PR drill-down, review rounds and reviewer load to find where a specific team is stuck, and they lean on Wooly for the cross-cutting questions a fixed dashboard never covered, such as why cycle time jumped in a particular sprint. Platform and developer-experience teams own the rollout. They care about integration coverage, attribution quality, and whether the same model really applies across every repository, including polyglot monorepos and acquired codebases that report differently. AI transformation and FinOps leads use Token Intelligence to connect Cursor, Copilot, Claude Code and agent spend to merged output, build a budget, and decide which seats to renew. Finance and procurement join that conversation when the question shifts from usage to cost per merged PR. Security, compliance and IT reviewers are a formal gate at larger companies. Weave markets SOC 2 Type II, GDPR, HIPAA, SAML and OIDC SSO, SCIM provisioning, audit logs, on-premise deployment and an air-gapped option, and quotes go-live in under two weeks, which matters to buyers who have watched competitor rollouts take a quarter. It fits less well for solo developers, agencies billing by the hour, or teams that want a lightweight standup bot. It is also a poor fit where engineering work happens outside connected repositories, because planning, mentoring and incident response are not captured by a diff score.
Weave Use Cases
Measure how much engineering work actually shipped last quarter without counting lines or pull requests.
Show the board what AI tooling spend bought in merged output and cost per PR.
Find which teams are slowed by review bottlenecks before delivery commitments start to slip.
Trace a production incident back to the pull request and commit that introduced it.
Decide whether to renew Cursor, Copilot or Claude Code seats using measured output per dollar.
Cut coding-agent costs by routing routine prompts to cheaper models through Weave Router.
Answer an executive question about cycle time in seconds instead of filing a data request.
Standardise engineering metrics across acquired teams that report in completely different ways.
Weave Pros and Cons
Pros
- One consistent output unit across engineers, repositories and languages makes team and org comparisons defensible.
- AI attribution is layered rather than guessed: native API data first, then commit metadata, with estimates labelled as estimates.
- The free Starter tier exposes output score, AI ROI and process metrics, so a team can test the numbers before paying.
- Go-live is quoted at under two weeks, with SOC 2 Type II, SSO, SCIM and an on-premise option for regulated buyers.
Cons
- Per-engineer scoring invites misuse as a performance rating, and Weave's own methodology warns the score is an estimate, not a time record.
- Pro at 50 dollars per engineer per month gets expensive at scale, and the useful drill-down views sit behind it.
- Coverage depends on integrations; tools without API access fall back to inferred or estimated attribution, and work outside connected repositories is invisible.
FAQ About Weave
Weave Pricing
Weave is freemium. Starter costs $0 with org-level output, AI ROI, code turnover and process metrics, Pro is $50 per engineer per month with PR drill-down, individual stats, Wooly and AI Insights, and Enterprise is custom. Yearly billing saves 16.67 percent. Weave Router is billed separately, from $10 per month.
Check official pricingStarter
Free forever for basic usage or teams under five: output score, AI ROI, code turnover, and org-level AI usage, process and quality metrics.
Pro
Adds PR drill-down, individual and team stats, Wooly AI agent, AI Insights and user permissions; billed monthly, or yearly at 16.67% off.
Enterprise
Security and compliance review, GitHub Enterprise support, a dedicated Slack channel, custom invoicing, DPA and terms, plus SSO, SCIM and on-premise deployment.
Weave Alternatives
Oogwai
Oogwai builds AI products that sit on top of business data and answer questions in plain English. Connect Google Analytics, Google Ads, Meta Ads, Shopify, YouTube Analytics or Tally, then ask about ROAS, conversion rate, retention or receivables. Every answer returns the figure, the chart and the source it came from, so marketing, e-commerce and finance teams can audit the working instead of rebuilding spreadsheets.
Trooly
Trooly is an AI-native qualitative research platform. It writes the research plan, screens and recruits participants, moderates one-on-one multimodal voice interviews, and synthesizes transcripts into themed reports. Product and research teams can bring their own users at $10 per interview, or let Trooly recruit from a network of 180M+ respondents, with every interview quality-checked before delivery.
Vert
Vert is a computer-vision parking operations platform for property managers, municipalities and parking operators. It pairs smartphone-based automatic license plate recognition with digital permits, guest registration, hourly and monthly payments, violation ticketing, appeals and reporting in one branded system. Teams scan plates on foot or by vehicle, check infractions against live permit and payment records, and issue digital or printed notices without separate camera hardware.